Architecture
Overview
Definity is an enterprise lakehouse optimization and observability platform. It connects to the enterprise data lakehouse and allows the data teams to monitor, optimize and protect their data infrastructure.
Definity can be deployed in 2 methods:
- A standard SaaS model hosted in the Definity's secure cloud environment. In this model metrics & metadata are reported to Definity servers.
What leaves your environment: metadata, execution metrics and query text. Query text includes SQL literals, which may contain data values. Unless spark.definity.privacy.enabled=true, diagnostic samples (a few key values from skewed tasks and the failing row) are also sent. No bulk data or query results are sent.
- A fully internal service deployment if security requirements will not allow SaaS access.
In internal mode the agents report to a server inside your network, so the data listed under Data Flow Summary stays on your premises. The Definity team has no access to the deployment or to reported metrics.
Components
Agents
Definity uses dedicated data pipeline agents that are added by configuration to each pipeline in the customer's data platform. The agents are provided as a code library (JAR File / Python library) and the agent code runs as part of the customer's data application. The agents communicate with Definity platform server either in the SaaS or internal deployment as selected.
The agents send metadata, metrics and query text to the server (see Data Flow Summary), and can receive instructions back from it. The server persists the metrics, runs analysis on the metrics to identify potential issues and optimizations in the user data pipelines, and exposes a web application for the pipeline owners.
Agent instrumentation
Definity agents are added to the data pipeline and run as part of the pipeline. Specific instrumentation info can be found in the relevant installation section.
Server
SaaS Deployment
Definity's platform server is hosted on Definity's cloud provider. All communications with the agents and the web application are TLS encrypted and authenticated with OAuth token.
What leaves your environment: metadata, execution metrics and query text. Query text includes SQL literals, which may contain data values. Unless spark.definity.privacy.enabled=true, diagnostic samples (a few key values from skewed tasks and the failing row) are also sent. No bulk data or query results are sent.
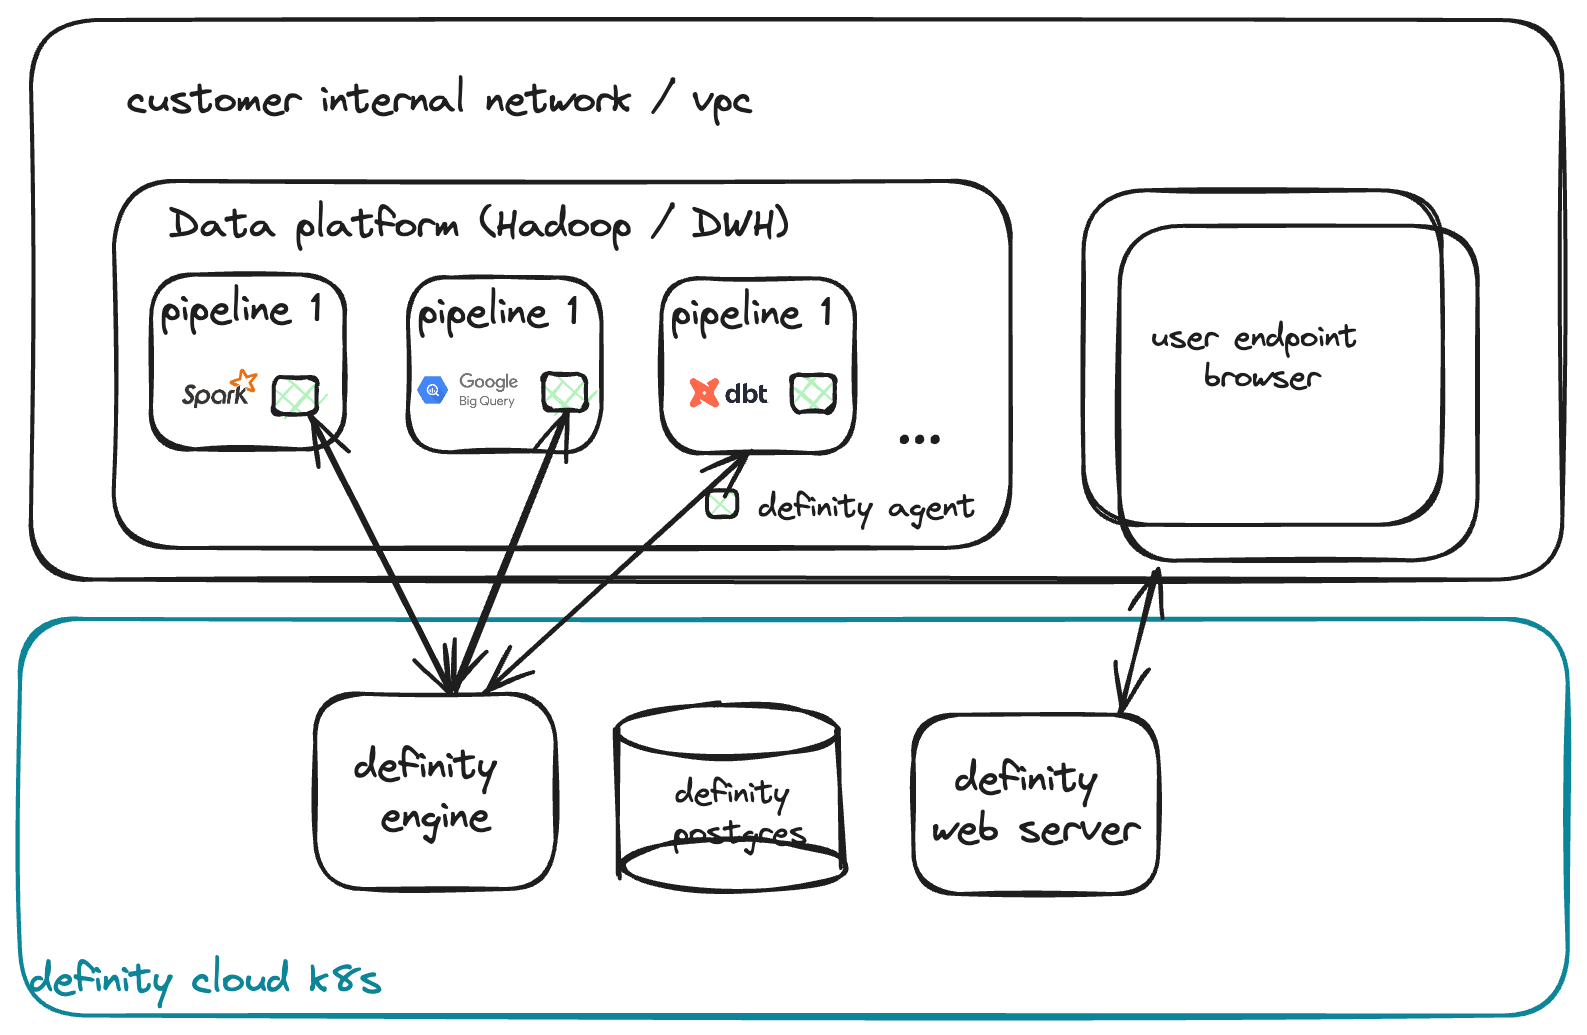
Customer's internal Deployment
Definity server can be deployed as a service in the customer internal network / VPC. Agents report to that server instead of Definity's cloud, so nothing they collect leaves the customer's premises, and the Definity team has no access to the deployment. This option requires a dedicated DevOps/champion to support server upgrades and maintenance.
The server deployment is provided as a standard helm / docker as described in the installation page.

Zero-Code Change integration
Definity achieves zero code change instrumentation via agent-based instrumentation:
-
The agent automatically hooks into pipeline runtimes (e.g., Spark, DBT) at execution time.
-
It extracts execution context, schema evolution, and metric data from runtime metadata.
-
No modifications to job code, SQL, or DAGs are required.
Data Flow Summary
-
Pipeline job starts in customer environment.
-
Definity agent attaches at runtime and observes job metadata.
-
Metadata, metrics, query text and (unless privacy mode is on) diagnostic samples are transmitted via TLS to Definity’s control plane.
-
Insights are stored, analyzed, and surfaced in dashboards and APIs.
From agent to server
| Data Type | Collected | Off with privacy.enabled | Notes |
|---|---|---|---|
| Pipeline Metadata | ✅ | Job name, start/stop time, run status, DAG/task IDs | |
| Schema Metadata | ✅ | Column names, data types, evolution history | |
| Execution metrics | ✅ | Duration, counts (including row counts), error rates, resource usage | |
| Column distribution statistics | ✅ | ✅ | Value histograms and other per-column statistics |
| Diagnostic samples | ✅ | ✅ | A few key values from the slowest tasks and the row a failed task was on (Spark) |
| Query text | ✅ | SQL and plans, including literals |
With spark.definity.privacy.enabled set to true, no row samples, skewed keys, column distribution statistics (including value histograms) or partition values are sent. Query text is not changed, so literals in a statement still reach the server.
No bulk data or query results leave the customer's environment.
From server to agent
The agent opens every connection, outbound over TLS. The server sends instructions back only as responses on those connections: it never connects into your network, and nothing listens for inbound connections on the agent side. The agent can act on these instructions:
| From server to agent | Purpose | Off with readOnly | Where to see it |
|---|---|---|---|
| Spark configuration overrides at task start | Auto-Tune | ✅ | The task run's Params tab (autotune.-prefixed rows) and the job's Auto-tune activity. See Review the changes Auto-Tune applied |
| Output diversion plan | Side-by-side validation runs | ✅ | — |
| Stop request | Break test action | ✅ | — |
| Databricks API calls from inside the job | Auto-Tune | ✅ | Your Databricks audit log (system.access.audit), under the identity the agent calls with |
| Data quality metric requests | Opt-in column metrics: extra queries, or Spark Observe on running ones | ✅ | — |
Set spark.definity.readOnly to true to turn all of these off. It can only be set in the job's own Spark configuration: the server cannot set or clear it. The server can request only these predefined operations; it cannot send the agent code or scripts to run.
If the agent loses contact with the server, or hits an error, a timeout or excess overhead, it disables itself and the job keeps running without it. No further instructions are applied to that run.
Every agent call to the server is logged on the server side.
Supported Runtimes and Targets
| Runtime / Platform | Support | Notes |
|---|---|---|
| Apache Spark (Kubernetes / YARN) | ✅ Full support | Versions & Details |
| Google Dataproc (Cluster & Serverless) | ✅ Full support | Integrated with GCP IAM and Dataproc APIs. Versions & Details |
| **Databricks ** | ✅ Full support | Versions & Details |
| Others | 🧩 Roadmap | Additional runtimes under evaluation. |
Security
Security, privacy and compliance are covered in the Trust Center.